EmoReco
AWRP encoding of EEG feeding a frozen DINOv2 ViT-B/14 backbone, evaluated on five public emotion datasets under one pipeline.
- DEAP
- SEED
- SEED-IV
- DREAMER
- FACED
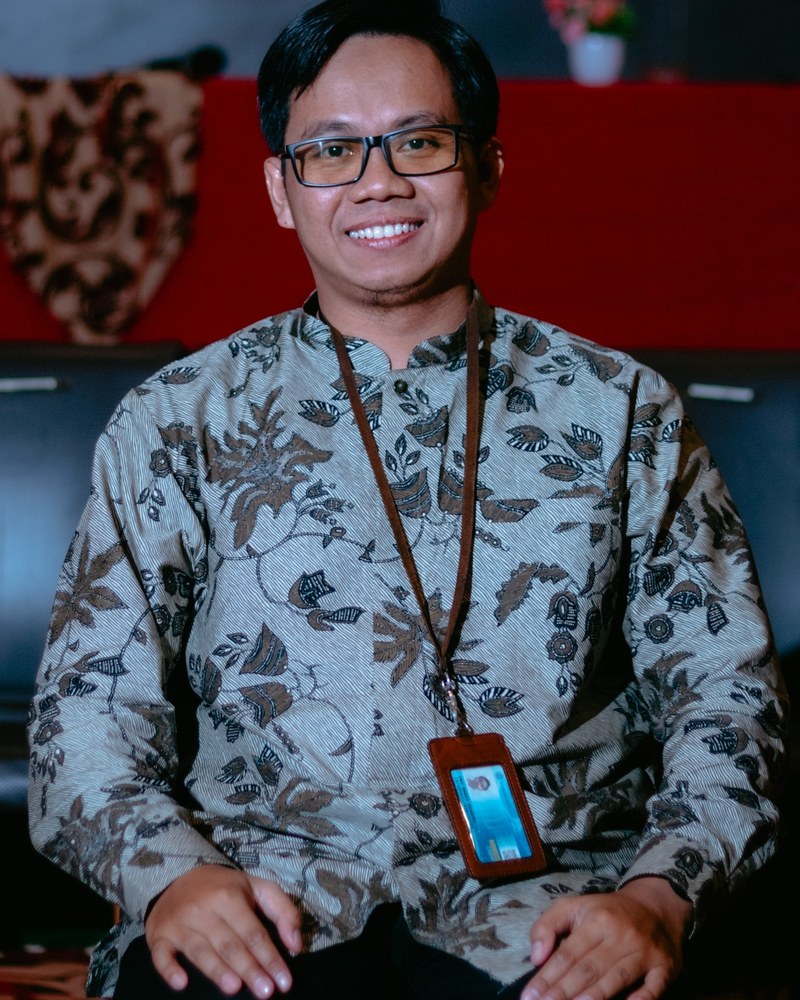
Dean, Faculty of Computer Science, Universitas Darwan Ali
Researcher in biomedical signal processing and applied AI.
Read Research & BlogDwi Wahyu Prabowo is Dean of the Faculty of Computer Science (Fakultas Ilmu Komputer) at Universitas Darwan Ali. He has taught since 2011 and has held academic management roles in research and community service (LPPM) and in the Information Systems program.
His research connects biomedical time-series analysis with modern vision backbones: encoding EEG into image representations, then testing how well those representations carry emotional state across subjects. In practice, he documents these technical methods so that complex analytical pipelines can be scrutinized and reproduced by students and fellow researchers.
Peer-reviewed work on EEG-based emotion recognition. Each title opens the paper through its DOI or publisher page.
AWRP encoding of EEG feeding a frozen DINOv2 ViT-B/14 backbone, evaluated on five public emotion datasets under one pipeline.
An academic electronic signature system for the Faculty of Computer Science at Universitas Darwan Ali, built for official faculty documents.
AIML-RG is led by Dr. Dwi Wahyu Prabowo as Coordinator. It is a center of excellence for applied computational research at Universitas Darwan Ali, covering biomedical signals (EEG/BCI), computer vision for local commodities, and compute-efficient deep learning.
EEG emotion recognition through spectrograms, recurrence plots (AWRP), and CNN-based spatial-temporal representations.
Image classification of agricultural and local commodities from Central Kalimantan using lightweight CNNs and YOLO object detection.
Lightweight deep learning architectures designed to be trained and fully reproduced on free cloud platforms (Google Colab / Kaggle).
Cross-cluster collaboration with the Data Science, Analytics & Decision Support Systems Research Group (DSDSS-RG), coordinated by Nurahman, M.Kom.
Five Research Groups operate in the Information Systems program:
Peer-reviewed journal articles and conference proceedings co-authored with undergraduate students under thesis mentorship in the Information Systems program.
Long-form notes with the mathematics and code left in. Open a note to read it here.
A complete walkthrough: phase space reconstruction, the recurrence matrix, asymmetric windowing against GASF and MTF, feature extraction for Vision Transformers, and a NumPy implementation.
Where leave-one-subject-out evaluation quietly leaks, what to report beyond mean accuracy, and an audit loop you can reuse.
Degrees, appointments, and professional certifications.
Department of Electrical and Information Engineering, Universitas Gadjah Mada
2024 · GPA 4.00
Department of Electrical and Information Engineering, Universitas Gadjah Mada
2014 · GPA 3.76
Universitas Indonesia
2011
Published Journal Paper: This note provides the mathematical foundation and reference implementation for the research study:
D. W. Prabowo, N. A. Setiawan, J. Debayle, and H. A. Nugroho, "Enhancing EEG-Based Emotion Recognition Using Asymmetric Windowing Recurrence Plots," IEEE Access, vol. 12, pp. 85969–85982, 2024.
IEEE Xplore (Doc 10547242) ↗ ·
DOI: 10.1109/ACCESS.2024.3409384 ↗
An EEG epoch is a short window of voltage samples across a few dozen channels. Feed it to a classifier as raw samples or band-power statistics and the model has to discover temporal structure that the representation never states. Asymmetric Windowing Recurrence Plots (AWRP) make that structure explicit: they turn each channel's recent dynamics into a matrix that records when the signal revisits states it has been in before.
This note walks through the mathematics, shows how the asymmetric window differs from the common GASF and MTF image encodings, explains how the resulting images become features for a Vision Transformer, and ends with a NumPy implementation. The version here is a simplified teaching reading. The exact windowing and parameters used in the experiments are specified in the IEEE Access paper (DOI: 10.1109/ACCESS.2024.3409384).
A band-power vector summarizes how much energy sits in each frequency band, and discards when it occurred. A raw sample vector keeps order but treats neighbouring samples as unrelated coordinates. Neither states the property that emotion studies usually care about: how the signal's trajectory behaves over time, whether it repeats, drifts, or settles. A recurrence representation puts that question first.
Take a single-channel series s1, s2, …, sN. Time-delay embedding lifts it into an m-dimensional space by stacking delayed copies of itself:
EEG is noisy and not a clean low-dimensional deterministic system, so the theorem is a motivation, not a guarantee. In practice the embedding is a representational tool, and small values such as m = 3 and τ = 2 are common in applied work. Each embedded point xi is a short snapshot of recent dynamics, not a single voltage.
A recurrence plot asks, for every pair of embedded points, whether the trajectory has come back close to where it was:
Here Θ is the Heaviside step function and ‖·‖ a norm, usually Euclidean. The result is a binary matrix. Two read-outs matter for classification:
The threshold ε decides how dense the image is. A fixed absolute ε makes images from high-amplitude and low-amplitude recordings look different for reasons unrelated to emotion. A common remedy is to set ε as a quantile of the pairwise distances, so that every matrix has the same recurrence rate:
Because distances scale with the signal and a quantile scales with them, the binary matrix is unchanged by a positive rescaling of the channel and by a constant offset. That property is useful when subject-to-subject amplitude differences are large, and it follows directly from the definition, with no appeal to experiments.
A standard recurrence plot compares a window with itself. Row i and column i refer to the same instant, so the matrix is symmetric, the main diagonal is trivially filled, and half the image repeats the other half.
Asymmetric windowing breaks that symmetry on purpose. Both windows end at the current sample t, but they differ in length: a short reference window of Wr samples is compared against a longer context window of Wc > Wr samples. Writing the embedded reference points as xi and the embedded context points as yj:
with nr = Wr − (m−1)τ and nc = Wc − (m−1)τ. This is a cross-recurrence matrix. It is rectangular, it is not symmetric, and it has no trivial diagonal. Each row answers one question: does the recent state appear anywhere in the longer past? The position of the filled cells along a row encodes how far back the revisit happened.
Gramian Angular Summation Fields (GASF) and Markov Transition Fields (MTF) are the usual alternatives for turning a series into an image. With the series rescaled to [−1, 1] and φi = arccos(s̃i):
In (6), q(·) assigns a sample to one of Q quantile bins and wab is the first-order probability of moving from bin a to bin b.
| Property | GASF | MTF | AWRP |
|---|---|---|---|
| Built from | Pairwise angular sums of rescaled amplitudes | Bin-to-bin transition probabilities | Distances between delay-embedded states |
| Uses a state vector | No, single samples | No, single samples and one-step transitions | Yes, m samples per point |
| Symmetric | Yes | Yes | No, rectangular by construction |
| Amplitude handling | Min-max rescale, sensitive to outliers | Quantile binning, amplitude within a bin is lost | Quantile threshold, invariant to scale and offset |
| Temporal structure | Relative to the diagonal | First-order Markov only | Revisits at any lag inside the context window |
The table states properties of the transforms. It does not rank them on accuracy. Whether AWRP wins on a given dataset is an empirical question, and it should be answered with the evaluation protocol in the companion note on LOSO audits.
The matrix is now an image, so a vision backbone can read it. The pipeline in EmoReco uses a frozen DINOv2 ViT-B/14:
Freezing the backbone keeps the trainable parameter count small, which matters when a dataset has only a few dozen subjects. The assumption doing the work is that texture statistics learned on natural images also separate diagonal-line and block patterns in recurrence images. Recurrence images are not natural images, so that assumption is tested by the experiments and is not guaranteed by the architecture.
The code below is plain NumPy for the encoding, followed by the feature extraction call. It is a compact teaching version, not the research code. The research code lives in the EmoRecoDino repository.
import numpy as np


def embed(s, m=3, tau=2):
    """Time-delay embedding, equation (1). Returns shape (n, m)."""
    n = len(s) - (m - 1) * tau
    if n <= 0:
        raise ValueError("signal too short for this (m, tau)")
    idx = np.arange(n)[:, None] + tau * np.arange(m)[None, :]
    return s[idx]


def cross_recurrence(ref, ctx, rate=0.10):
    """Binary cross-recurrence, equation (4).

    The threshold is the `rate` quantile of all pairwise distances,
    so every image has the same recurrence rate, equation (3).
    """
    d = np.linalg.norm(ref[:, None, :] - ctx[None, :, :], axis=-1)
    eps = np.quantile(d, rate)
    return (d <= eps).astype(np.float32)


def awrp(x, m=3, tau=2, w_ref=128, w_ctx=256, rate=0.10):
    """x: (channels, samples). Both windows end at the last sample.

    Returns (channels, n_ref, n_ctx).
    """
    out = []
    for ch in x:
        ref = embed(ch[-w_ref:], m, tau)
        ctx = embed(ch[-w_ctx:], m, tau)
        out.append(cross_recurrence(ref, ctx, rate))
    return np.stack(out)


def to_vit_input(img, size=224):
    """Nearest-neighbour resize to (3, size, size) by index sampling."""
    rows = np.linspace(0, img.shape[0] - 1, size).astype(int)
    cols = np.linspace(0, img.shape[1] - 1, size).astype(int)
    plane = img[np.ix_(rows, cols)]
    return np.repeat(plane[None], 3, axis=0)


if __name__ == "__main__":
    rng = np.random.default_rng(0)
    eeg = rng.standard_normal((32, 512))        # 32 channels, 512 samples
    maps = awrp(eeg)                            # (32, 124, 252)
    batch = np.stack([to_vit_input(mp) for mp in maps])
print(maps.shape, batch.shape) # (32, 124, 252) (32, 3, 224, 224)import torch
# Frozen DINOv2 ViT-B/14; the model returns the class-token embedding.
model = torch.hub.load("facebookresearch/dinov2", "dinov2_vitb14").eval()
mean = torch.tensor([0.485, 0.456, 0.406]).view(1, 3, 1, 1)
std = torch.tensor([0.229, 0.224, 0.225]).view(1, 3, 1, 1)
with torch.no_grad():
x = (torch.from_numpy(batch) - mean) / std # batch from awrp.py
z = model(x) # (32, 768), one row per channel
sample_feature = z.mean(dim=0) # pool channels, shape (768,)The mathematics above explains why a recurrence encoding is a reasonable input: it states temporal structure, it is insensitive to amplitude scale, and it exposes revisits at several lags. It does not by itself show that the encoding generalizes to unseen people. That claim depends on how the experiment is split, which is the subject of the companion note.
Treat any single accuracy figure as incomplete until you know the split protocol, the normalization scope, and the per-subject spread.
Emotion recognition from EEG is usually reported as a single accuracy. For a system meant to work on people it has never seen, that number is only meaningful if the evaluation separated people cleanly. Leave-one-subject-out (LOSO) is the standard protocol for that, and it is also easy to run in a way that leaks.
For S subjects, train on S − 1 of them and test on the one held out, then repeat for every subject. The reported score is the mean over folds, and the spread across folds belongs next to it:
The function below makes the scope of every step explicit. Scaling statistics come from training subjects only, and the output keeps the per-subject scores so the spread cannot be dropped by accident.
import numpy as np


def loso_audit(X, y, subjects, make_model):
    """X: (n, d) features, y: (n,) labels, subjects: (n,) subject ids.

    make_model must return a fresh estimator with fit/predict.
    """
    scores = {}
    for s in np.unique(subjects):
        test = subjects == s
        train = ~test

        # Scaler sees training subjects only.
        mu = X[train].mean(axis=0)
        sd = X[train].std(axis=0) + 1e-8

        model = make_model().fit((X[train] - mu) / sd, y[train])
        pred = model.predict((X[test] - mu) / sd)
        scores[s] = float((pred == y[test]).mean())

    acc = np.array(list(scores.values()))
    return {
        "mean": acc.mean(),
        "std": acc.std(ddof=1),
        "worst": min(scores, key=scores.get),
        "per_subject": scores,
}A representation that gains a few points in a random split and loses them under LOSO was fitting subject identity. A representation that keeps its gain, with a narrow spread across subjects, is the one worth building on. Reporting both numbers makes that difference visible to the reader.
For encodings such as AWRP, run the LOSO audit before drawing conclusions from the images. The method is described in the featured deep-dive.